Assignment 4
Due: Monday, June 9 at 11 AM ET to be submitted via Crowdmark
Note: Your submitted solution must be unique and written in your own words; if you collaborate with other students, external resources, and/or use AI tools, this must be clearly acknowledged in your submission.
Part 1
This assignment covers material from Chapters 23-29 of R4DS / Chapters 25-31 of P4DS. Please complete the ALL of following exercises.
- Write a custom function to compute the variance of a numeric vector.
- Using the
flightsdataset, write a function calledfilter_severethat finds all flights that were cancelled or delayed by more than a user supplied number of hours (i.e.filter_severe(flights, hours = 2)) - Use
dplyr::acrossorpandas.applyon thepenguinsdataset to compute the mean of each column. - Group the
penguinsdataset byspeciesand save each group as a separate.csvusing an iteration method.
Part 2
Import
- Hierarchical/Nested Data: Reddit is an excellent source of data for sentiment analysis and natural language processing. In the case of sports, we can use reddit to perform fan sentiment analysis.
Find a thread from the subreddit of your favourite sports team. Add “.json” to the end of the url, which will convert the page to JSON. Read this data and convert the thread metadata to a dataframe with the following columns:
| subreddit | permalink | author | title | created_utc (timestamp) | num_comments | ups (upvotes) | downs (downvotes) |
Your resultant dataframe should only have 1 row.
For example, if the url is https://www.reddit.com/r/torontomapleleafs/comments/1kvy0su/i_figured_out_the_recipe_for_a_stanley_cup/,
The new url will be https://www.reddit.com/r/torontomapleleafs/comments/1kvy0su/i_figured_out_the_recipe_for_a_stanley_cup.json.
My resultant dataframe will look like
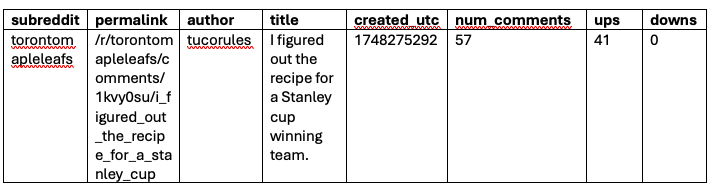
- Webscraping: Using a subsidiary page of Sports Reference (such as Baseball-Reference or Hockey-Reference), scrape one table of career statistics of one player by:
- using the default
rvest::html_table()orpd.read_htmlcommands. - using CSS selectors/HTML tags (
tr,td,thead, etc)
- using the default
Confirm that these two tables are identical, and perform appropriate tidying and data cleaning.
- Databases: Using
duckdb, create an in-memory database of the scraped table. Perform a sample query using aselect, awhere, andaggregation(i.e. min, max, count, sum, avg) statements.
Communicate
- Use Quarto to make a static GitHub Pages site (like THIS) using the analysis from Part 2 of Assignments 1-3. Please submit the link to the site as part of this assignment. If you have GitHub Pro (free through GitHub Education, for example), the associated github repository can be private, otherwise the repository must be public for the webpage to properly deploy.